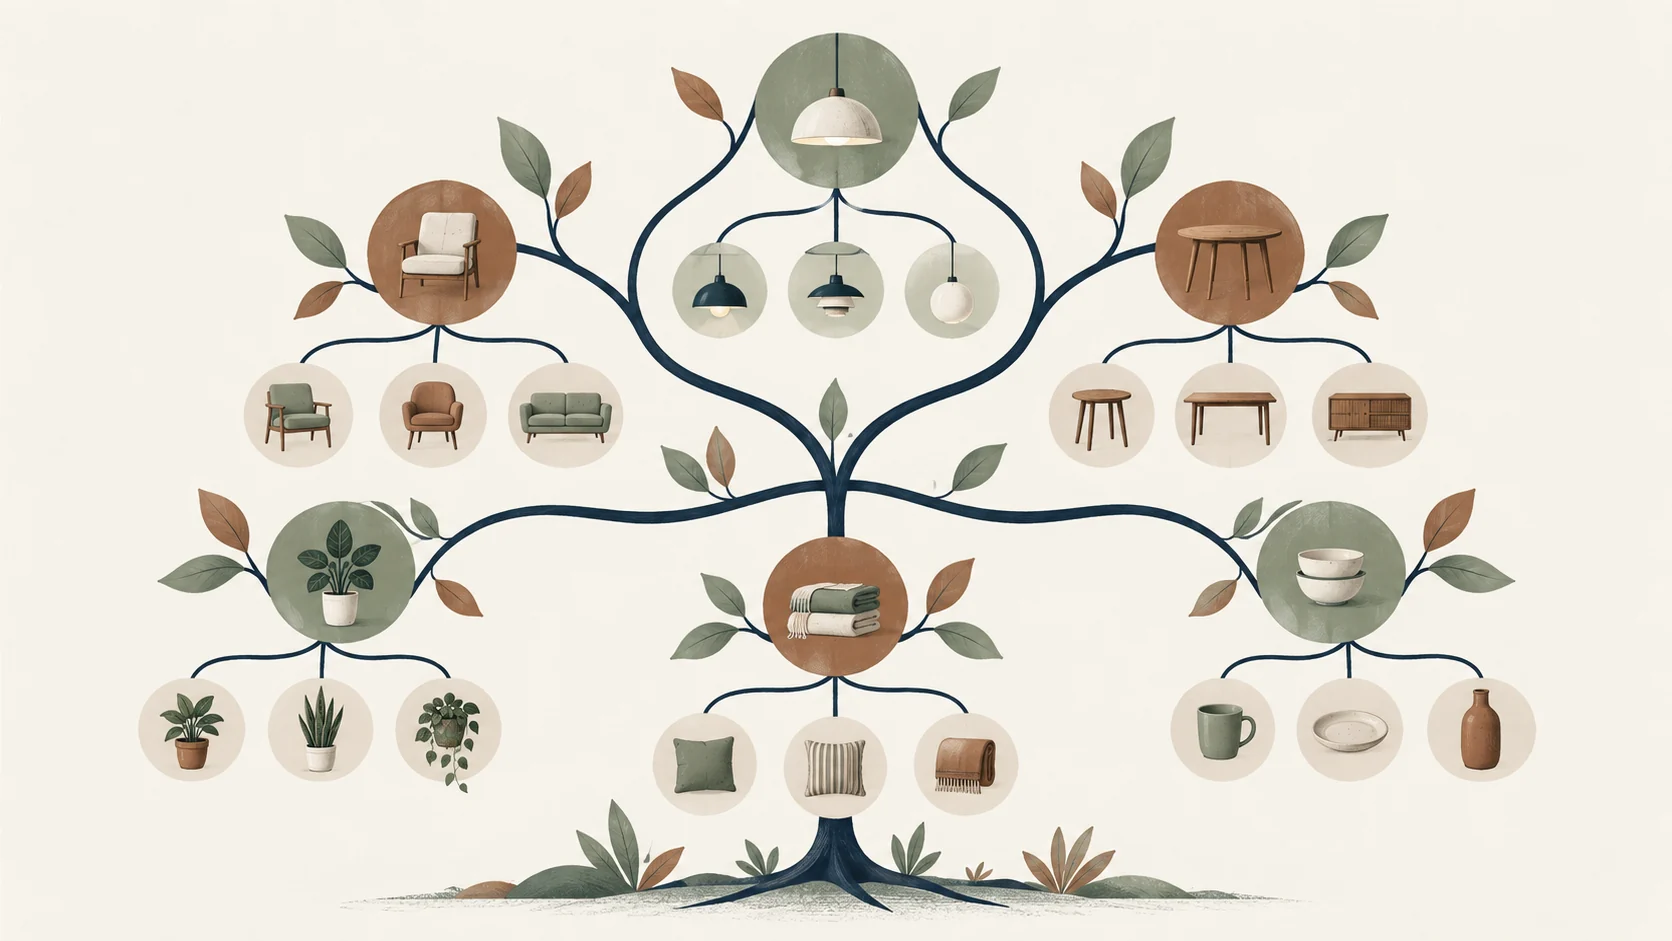
A shopper searches for a lamp that works in a small room. The catalogue contains the lamp, but the product information describes it differently in three places. One listing leads with the material. Another leads with the style. A third has the right photograph but leaves out a useful dimension. The product exists. A dependable description of it does not.
This is an illustrative situation, not a reported customer incident. It shows why I approach product AI through the information underneath it. A model can write an attractive sentence. It cannot make conflicting source material reliable simply by sounding certain.
My product-ontology work explored a GenAI-assisted approach to managing product information, validation, images and content distribution. The work was solution design. It was not a production deployment, and I do not present projected efficiency, revenue or compliance benefits as measured results. The useful part to share is the decision structure: how to decide what a product means before asking AI to describe it.
Begin with the product decision, not the model
The first question is what someone needs to decide. A shopper may be comparing dimensions. A category manager may be grouping similar products. A content team may need to prepare a listing for a marketplace. These are related uses, but they are not the same task.
That difference matters because a catalogue can look complete while remaining unhelpful. A record may have many fields and still omit the one that changes a purchase decision. It may contain a long description while leaving the relationship between a base product and its variants unclear. Counting populated fields does not tell us whether the information serves the person using it.
I would start by choosing a narrow category and a few real information journeys. How does a supplier's description become a product record? How does that record become a customer-facing listing? How does a correction reach every place that used the earlier information? The goal is to understand the route from evidence to a decision, rather than build a large field list and call it a strategy.
A small, explicit scope is useful. It gives the team a place to disagree constructively. When people discuss a particular category, they can point to an actual ambiguity. When the discussion stays at the level of an enterprise catalogue, everyone can agree while imagining something different.
Give the catalogue a shared language
I use ontology here to mean a deliberate account of product types, attributes and relationships. The label matters less than the decisions it makes explicit. Which characteristics distinguish one product from another? Which values are permitted? Which relationships help a person understand the product?
A category hierarchy answers where an item belongs. An attribute describes something about it. A relationship connects it to another item or concept. Those distinctions should not disappear into a single block of marketing text. A chair can have a material, belong to a furniture category and relate to a matching table without those three things being interchangeable.
The point is not to make the catalogue academically elaborate. It is to stop meaning from moving unnoticed between teams. If one team treats colour as a variant and another treats it as a descriptive attribute, the disagreement will eventually surface in search, inventory, content or customer support. A shared definition makes that disagreement visible before it becomes a customer-facing inconsistency.
I would document a small set of examples and non-examples. What belongs in this category? What looks similar but does not belong? Which attributes are essential, and which are optional? Examples give abstract definitions a practical test. They also make it easier for a person reviewing an AI suggestion to explain why it is wrong.
Separate identity from presentation
A product's identity should not change merely because its description is adapted for another channel. The same item might need a short title, a detailed page, a structured marketplace listing and a promotional image. Those are presentations of the product, not separate sources of truth about what it is.
Consider an illustrative product with several size options. If every channel creates its own version of the size description, a correction can become a search through unrelated copies. If identity and variant relationships are clear, the team has a better chance of understanding which presentations depend on the corrected record.
This is why I would keep channel-specific content separate from the underlying facts. The central record can hold approved attributes and evidence. A channel layer can decide how to express those facts within its own format. AI may help with expression, but it should not silently change the identity, dimensions, intended use or other approved characteristics.
The boundary also helps teams avoid a common misunderstanding: a fluent rewrite is not a data correction. If the source says two incompatible things, the problem belongs with someone who can determine which is right. Rephrasing the conflict does not settle it.
Ask what supports each important fact
Product information becomes more useful when the team can explain where it came from. A supplier document, an approved specification and a marketing draft do not carry the same authority. They may all contribute to a workflow, but they should not be treated as interchangeable evidence.
I would make provenance part of the product record. For an important attribute, the reviewer should be able to find the supporting source, see when it was checked and know who can answer a question about it. This does not require exposing internal documents to the shopper. It requires an internal route from the claim back to its basis.
An unresolved attribute should remain unresolved. If a model fills an empty field with a plausible value, the catalogue can look more complete while becoming less trustworthy. A visible gap is often safer than a confident fabrication, especially when the information changes a customer's choice.
There is a useful product-design question here: can the workflow distinguish missing, disputed, outdated and approved information? Those states require different actions. Treating all of them as blank fields invites the wrong kind of automation. A disputed value needs review. An outdated value needs a freshness check. A genuinely optional value may need no action at all.
Put AI where its contribution can be checked
My source material considered AI-assisted entry, validation, categorisation and channel adaptation. I would evaluate those capabilities separately. A model that writes a clear description is not automatically suitable for deciding category membership. A system that extracts a value from a document is not automatically suitable for approving it.
A sensible early task is to propose a structured record from a supplied document while preserving the source passages behind the proposal. A reviewer can then compare the suggestion with the evidence. The model's work is visible and bounded, rather than hidden inside a final listing that appears already approved.
Another task is to identify inconsistencies across records. Even then, an inconsistency report is a prompt for investigation, not permission to change every affected item. Two values may differ because one is wrong, because the products are genuinely different or because the categories use different conventions.
The important design choice is how the system handles uncertainty. Does it flag a question? Does it leave the field alone? Does it ask for review? An AI workflow that only has a success path will push ambiguous cases toward false certainty. I would rather make the review path part of the product from the beginning.
Keep images connected to the same truth
The design work also considered product-image preparation and external image tools. Images deserve the same care as text. An appealing image that implies an unsupported feature can create a misleading product presentation even if every written field is correct.
I would separate approved source images from generated or edited presentations. The team should know which image depicts the actual item, which is a crop or background treatment and which is illustrative. A change to an image should not erase that distinction. The review should ask whether the presentation still supports an honest understanding of the product.
Image and text review also need to meet. If the description promises one variant while the image shows another, checking them in separate queues may miss the contradiction. The customer receives a combined page. The workflow should therefore include a combined-page review at the point where the information is about to count.
This is not an argument against useful image automation. It is an argument for deciding what may change and what must remain faithful. The better the boundary, the easier it is to let routine preparation happen without making reviewers carry every detail in their heads.
Make the human review specific
“Human in the loop” is too vague to be a product requirement. It does not say who reviews, what they inspect or what authority their approval carries. A content reviewer may be able to improve wording without being able to approve a technical claim. A category owner may understand classification without owning a policy-sensitive statement.
I would define review responsibilities around the decision. Who can approve the attribute? Who can approve the channel presentation? Who handles an exception? What happens when those people disagree? These questions become especially important when AI makes a large number of suggestions quickly.
A useful review screen should show the proposed change, the current approved value and the supporting evidence together. The reviewer should not have to reconstruct that comparison across several tools. The system should also record why a suggestion was rejected, so the team can distinguish a model error from an unclear rule or an incomplete source.
The purpose is to make review effective, not merely present. A queue that encourages people to click through suggestions without enough context adds ceremony while leaving the risk intact. Smaller batches, clear ownership and well-chosen evidence can be more useful than a broad claim that every change was reviewed.
Treat compliance as an owned responsibility
Some product information is subject to channel rules or other external requirements. My concept material discussed that risk, but a public design record should not turn those broad notes into a legal assurance. Requirements vary by product, audience and destination. The applicable rules need their own current sources and qualified owners.
AI can help organise the material for review. It can flag a missing field against an approved checklist or prepare a comparison between an existing description and a proposed one. It should not be presented as independently guaranteeing compliance simply because it generated a checklist.
I would keep the rule source, its scope and the person responsible for applying it visible in the workflow. A change in a channel's requirements is then a reviewable event, rather than a mysterious instruction that affects every product. The team can determine which records are affected and what evidence is needed before publishing changes.
This is also where careful language matters. “Ready for review” and “approved for publication” are different states. A tool should not blur them. Customers and colleagues should receive the result of an owned decision, not the output of an unfinished process disguised as a final answer.
Design distribution as a feedback loop
A catalogue correction is not finished when the central record changes. It is finished when the relevant destinations have received the right information and any exceptions are understood. That is the distribution problem underneath content syndication.
In an illustrative workflow, a product team corrects a material description. One channel accepts the update. Another rejects it because its field format differs. A third still displays an older version. If the workflow reports only that the central save succeeded, the team may believe the problem is solved while the customer continues to see inconsistent information.
I would therefore distinguish prepared, sent, accepted and verified states. The design does not need to expose every technical step to every user, but it should make the remaining work clear to the people responsible. A rejected update needs a reason and an owner. A delayed update needs a visible status, not a hopeful assumption.
The feedback loop is part of product information management, not an optional reporting layer. It tells the team whether its approved facts have actually reached the customer-facing places where those facts matter.
Test the workflow before promising the benefit
My source documents contain proposed measures and ambitious benefit statements. I treat those as ideas for evaluation, not evidence that the design delivered a result. A useful pilot should establish a baseline, define what is being compared and account for the review work as well as the generation work.
I would choose a small but varied sample: straightforward records, incomplete records, conflicting source documents and cases that should be escalated. A demonstration that only uses clean examples can prove that the system handles clean examples. It says little about the situations that consume a team's time.
Measure correctness at the attribute and relationship level, not only whether a description sounds good. Track the reasons suggestions are rejected. Observe how long reviewers need to reach a dependable decision. Check whether the same information remains consistent after it moves to another channel. These measures describe the actual workflow rather than reward the model for producing more text.
There should also be a clear stopping rule. If a class of suggestions creates more correction work than it removes, keep that task under human control while investigating the cause. Scaling an unreliable step only spreads the problem faster.
What I would take into the next conversation
I would bring a sample category, a few representative records and a map of the decisions that connect source material to publication. I would ask which information failures hurt most, which sources are dependable and where a correction currently gets lost. Those answers would shape the first experiment more than a preferred model name.
The aim is not a catalogue that looks busy with automation. It is a catalogue that people can understand, maintain and trust. AI becomes useful when its contribution fits that responsibility. The product ontology gives the contribution somewhere coherent to land.
This remains a design perspective, not a claim of a deployed client result. If a team wants to explore it, I can help frame the category, evidence, review and distribution decisions before the implementation grows. Start with what must be true about the product. Then decide where AI can help without making that truth harder to inspect.
Related reading: Building a product ontology: a practical how-to for retail teams.